Distribution-aware Scaling
Rescales linear outputs into a range that supports neuron activity and gradient propagation. The scaling parameters can be fused into the preceding linear layers for inference.
EFFICIENT AI / RESEARCH PROJECT
SpikingLM: Towards Fully Spiking Language Model
Bringing language understanding to fully spiking computation.
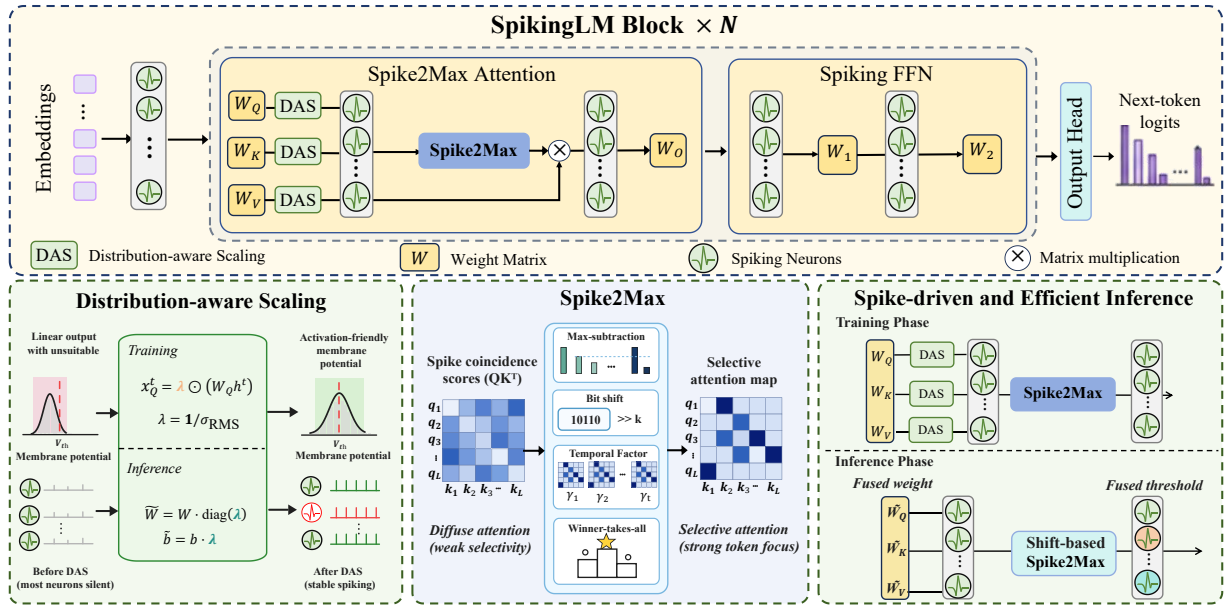
SpikingLM addresses two obstacles in deep spiking language models: inactive neurons that weaken gradients, and the loss of token competition when Softmax is removed. It combines Distribution-aware Scaling with Spike2Max to improve training and attention while retaining efficient computation.
Rescales linear outputs into a range that supports neuron activity and gradient propagation. The scaling parameters can be fused into the preceding linear layers for inference.
Restores competition between tokens using base-2 exponentiation and max-subtraction, enabling efficient bit-shift operations.
lower energy consumption reported in the paper's evaluation
energy reduction for Spike2Max compared with Softmax
The paper evaluates language understanding on GLUE. See the paper for model configurations, energy assumptions and comparisons.
Results and experimental details ↗@inproceedings{pmlr-v306-liang26ae,
title = {{SpikingLM}: Towards Fully Spiking Language Model},
author = {Liang, Yu and Zhou, Zijian and Wei, Wenjie and Wang, Shuai and Cao, Honglin and Belatreche, Ammar and Yang, Yu and Zhang, Malu and Yang, Yang and Li, Haizhou},
booktitle = {Proceedings of the 43rd International Conference on Machine Learning},
series = {Proceedings of Machine Learning Research},
volume = {306},
pages = {73744--73762},
year = {2026},
url = {https://proceedings.mlr.press/v306/liang26ae.html}
}